Every story, with its video
Each week's video is written up here story by story, with the numbers in it and where each one is from. The newest is first.
RTX Spark Laptop vs DGX Spark: Buy or Wait? On YouTube
 Plays here, from YouTube
RTX Spark laptops are on sale: $2,599 to start, $5,899 for 128GB
Microsoft opened orders on Wednesday and five other makers follow on 16 October. The 128GB version is the one that runs the big models, and I would wait for independent tests before buying one.
Four DGX Sparks twice as fast at ordinary writing: the recipe, and a real session
I moved my four DGX Sparks to a recipe that another owner published on GitHub, and ordinary writing roughly doubled on the same hardware and the same model. The recipe is only a few weeks old, and these are one owner's figures from one cluster.
DGX Spark vs RTX Spark laptop: ports, price, and what joins up
Microsoft's RTX Spark laptop now costs less than NVIDIA's own DGX Spark with the same memory. The DGX Spark is the one that can be joined to other boxes, and I do not know yet how many of the recipes its owners share will work on Windows.
$4,999 DGX Spark vs M5 Ultra Mac Studio On YouTube
 Plays here, from YouTube
NVIDIA's 64GB DGX Spark at $4,999: what it runs
NVIDIA announced a DGX Spark with 64GB of memory, half of what the original has, and it costs more than the full one did at launch. The price is the part that stood out to me, and I could not find how NVIDIA measured the gain it claims from linking two or four together.
M5 Ultra Mac Studio vs my four DGX Sparks: the same model
MacStories tested GLM 5.3 Flash, the model my cluster runs, on a 256GB M5 Ultra Mac Studio, in a review I had missed. One Mac Studio writes about as fast as my four DGX Sparks and my Sparks read a prompt 2.04 times as fast, but the comparison is a rough one.
Anthropic's report on GLM 5.3: what its tests found
Anthropic published a security report on GLM 5.3, the family of open models my Sparks run. By Anthropic's count the model turned a known Chrome flaw into a working attack in 50 of 410 attempts, and as far as I could see on 3 October nothing had changed for anyone running it at home.
Are 4x M5 Ultra Mac Studios faster at AI than 1? On YouTube
 Plays here, from YouTube
Mac Studio M5 Ultra 512GB, and Apple's 3x cluster claim checked
Apple says its latest Mac Studio can hold 512GB of memory in one box, the same as my whole cluster of four DGX Sparks, and that a cluster of Studios runs AI up to 3x faster than one. I looked up how Apple measured that, and I would wait for independent measurements before ordering.
MiMo-V2.6 tops the open-weights board, and runs on DGX Sparks
Xiaomi's MiMo-V2.6-Pro sat at number one on Artificial Analysis's open-weights leaderboard on 27 September, and DGX Spark owners had both versions running within days. One owner reported 68.3 tokens a second on eight Sparks with speculative decoding, up from 17.8, and the early problem was tool use.
Hugging Face Transformers now loads GGUF: the catch
Hugging Face says its Transformers library can now load the GGUF files that llama.cpp made popular for running models at home. For now it only keeps the file compressed for some Qwen models on Apple silicon, and I think it is most useful to people who work in Python.
DeepSeek V4.1 Flash on 2 DGX Sparks! On YouTube
 Plays here, from YouTube
DeepSeek V4.1 Flash on 2 DGX Sparks, and the 2GB memory unlock
One of the regular recipe authors on NVIDIA's developer forum published a way to run DeepSeek V4.1 Flash on two DGX Sparks instead of four, with a second trick that applies to any headless Spark. I had not run it myself, and the speeds and the one quality check were the author's own.
Ternary Bonsai 2: a 27B model in under 6GB
Prism ML released a 27 billion parameter model built from Qwen 3.8 with every weight set to -1, 0 or +1, and says that brings it under 6GB. The maker says it keeps 98.2% of the original's scores, and on 19 September that was still the maker's own number.
Why a business bought 4 DGX Sparks: OpenFaaS's month with them
OpenFaaS, a UK software company, has written up why it spent about £10,000 on four DGX Sparks: customer data it will not send to a cloud provider, and red teaming its own products. It also found two 4-bit builds of GLM 5.3 Flash running at different speeds, so two builds of the same model are not interchangeable.
DeepSeek V4.1 Flash on 4 DGX Sparks, and the M5 Ultra Wait On YouTube
 Plays here, from YouTube
DeepSeek V4.1 Flash on 4 DGX Sparks: the 552B open model
DeepSeek released a 552 billion parameter model with open weights on 10 September, and within a day an owner had it running on four DGX Sparks. The speeds were similar to GLM 5.3 Flash on my own four, but they came from one owner's first day on a four bit build that had not been checked for quality, as far as I could see.
M5 Ultra Mac Studio wait times: 16 to 18 weeks for the full chip
On 11 September Apple's own store was quoting 16 to 18 weeks for any Mac Studio with the full M5 Ultra chip, which meant January. The 512GB option, the one Mac that could hold a four bit build of DeepSeek V4.1 Flash, could not be ordered at all.
NVIDIA's NVFP4 builds of GLM 5.3 Flash: 18 checked for the fault
NVIDIA published its own NVFP4 build of GLM 5.3 Flash on 9 September. I checked 18 builds of that model and of Qwen 3.8 Flash Next for the fault I had found on my own cluster, and found it in three GLM builds, the most downloaded one among them, and in neither of NVIDIA's own.
RTX Spark Ships in October, and NVIDIA Buys Hugging Face On YouTube
 Plays here, from YouTube
RTX Spark: October launch, PAIR routing, a free RTX speed-up
NVIDIA confirmed at IFA in Berlin that RTX Spark PCs would ship in October, and released PAIR, a free tool that spreads AI work across the PCs on a home network. Nobody outside NVIDIA had benchmarked an RTX Spark, and I think the free speed-up for RTX cards mattered more on the day.
NVIDIA buys Hugging Face for $12.93 billion: what it means
NVIDIA agreed to buy Hugging Face for $12.93 billion. For those of us running models at home that is our main supplier being bought by our hardware vendor, and I would make sure any model I rely on also lives on my own disk.
Qwen3.8 Flash Next and GLM 5.3 Flash on DGX Spark: first speeds
By 6 September owners on NVIDIA's forum had Qwen3.8 Flash Next running on a single DGX Spark at 37 to 44 tokens a second, and one post had GLM 5.3 Flash on one box at 64. The 64 came from a build squeezed to about 2 bits per weight, and I would want to see the quality numbers before copying it.
2x DGX Spark vs Apple M5 Mac Studio Ultra: What the Benchmarks Miss On YouTube
 Plays here, from YouTube
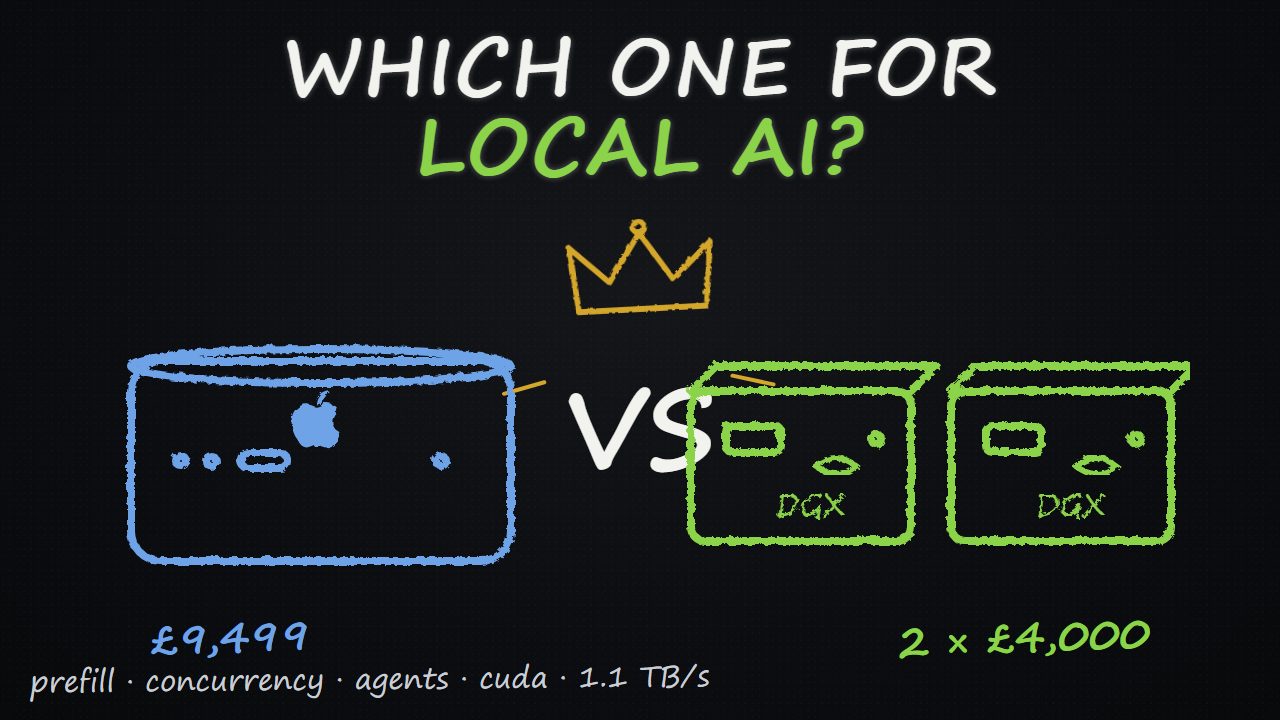
Two DGX Sparks or a Mac Studio Ultra: the same 256GB, the numbers side by side
A buyer with two new DGX Sparks asked on Reddit whether to send them back now that Apple had announced the M5 Ultra Mac Studio. I put my own cluster's numbers next to what Mac Studio owners measure, and I think the answer depends on the work: short questions suit the Mac, and agents and long documents suit the Sparks.