Local AI, timed on machines I own
I run AI models at home on hardware I bought myself, and I publish what I measure: which model, on which machine, how fast, and how it was timed.
The latest video Every video
 Plays here, from YouTube
RTX Spark Laptop vs DGX Spark: Buy or Wait?
A short video each week on what changed for people who run AI models at home. The stories in this one:
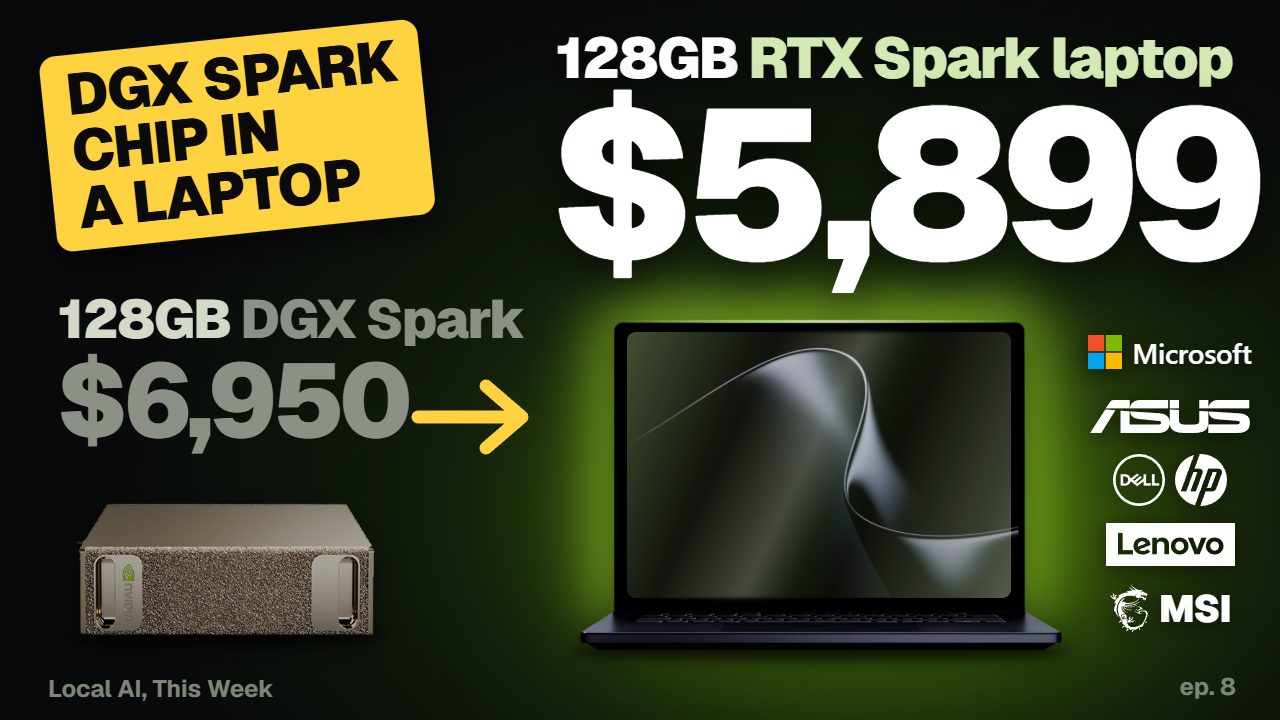
- RTX Spark laptops are on sale: $2,599 to start, $5,899 for 128GB
- Four DGX Sparks twice as fast at ordinary writing: the recipe, and a real session
- DGX Spark vs RTX Spark laptop: ports, price, and what joins up
Earlier stories All stories
NVIDIA's 64GB DGX Spark at $4,999: what it runs
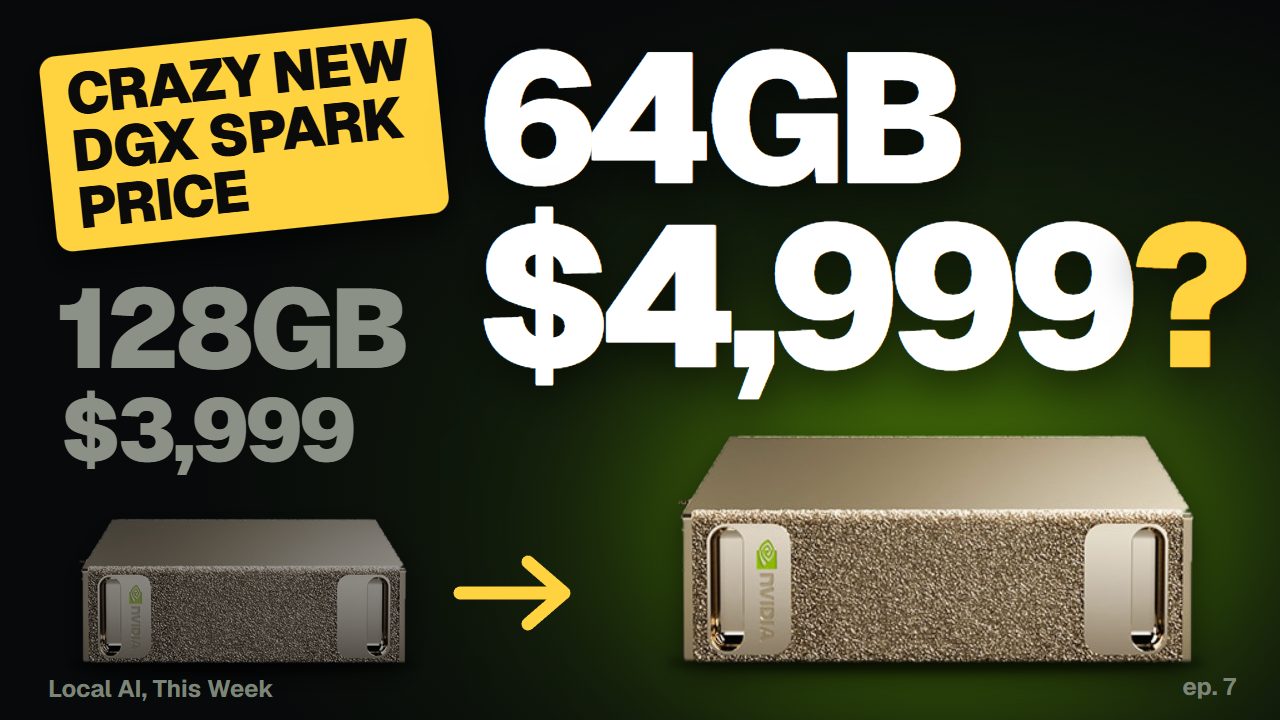
NVIDIA announced a DGX Spark with 64GB of memory, half of what the original has, and it costs more than the full one did at launch. The price is the part that stood out to me, and I could not find how NVIDIA measured the gain it claims from linking two or four together.
Mac Studio M5 Ultra 512GB, and Apple's 3x cluster claim checked
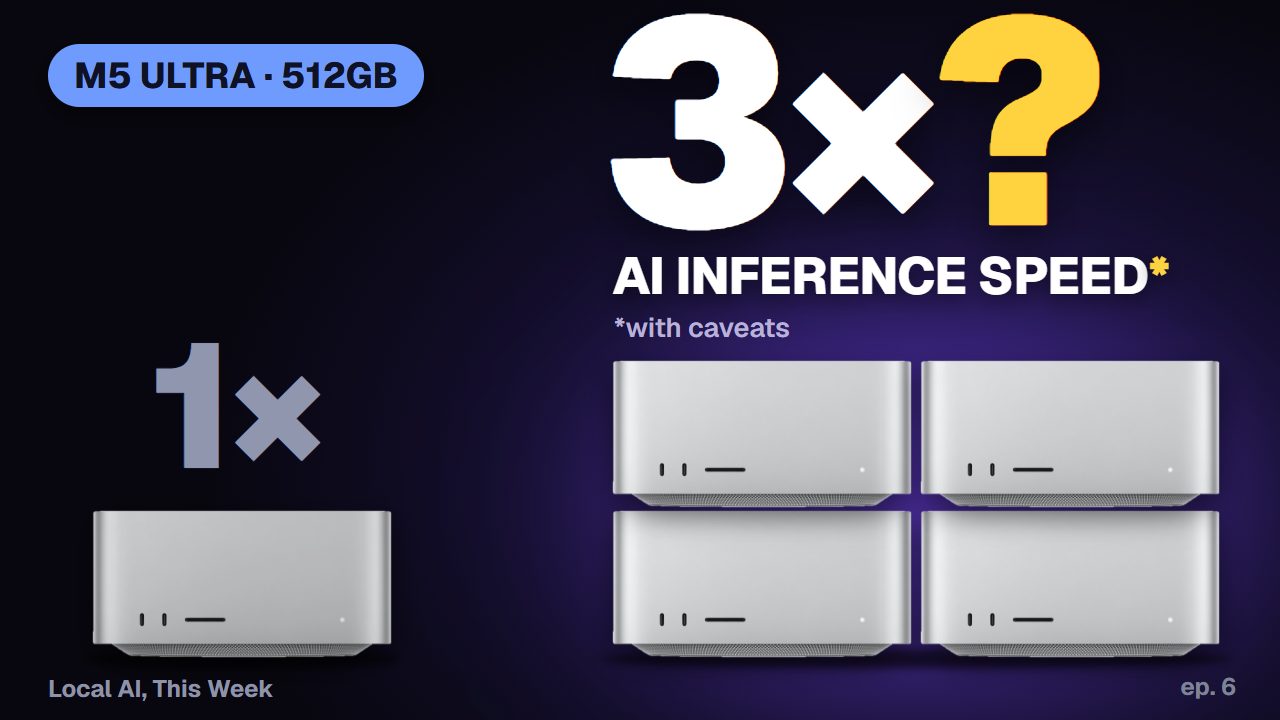
Apple says its latest Mac Studio can hold 512GB of memory in one box, the same as my whole cluster of four DGX Sparks, and that a cluster of Studios runs AI up to 3x faster than one. I looked up how Apple measured that, and I would wait for independent measurements before ordering.
DeepSeek V4.1 Flash on 2 DGX Sparks, and the 2GB memory unlock
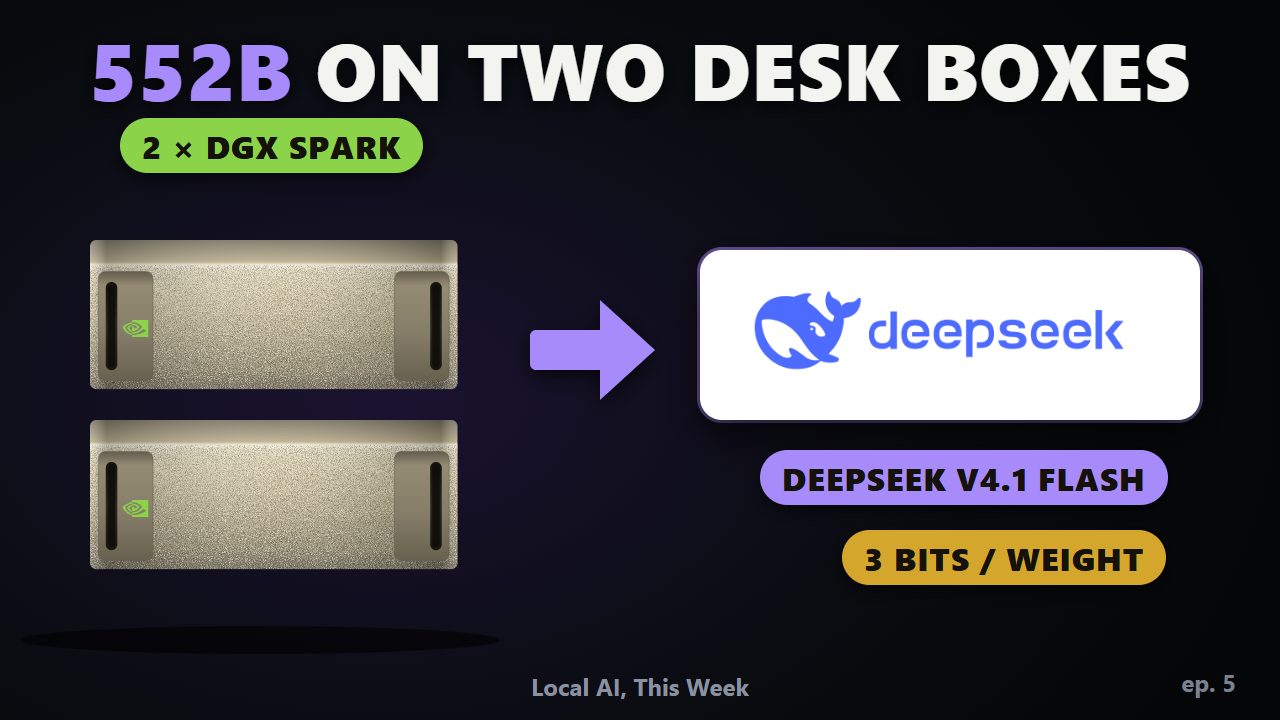
One of the regular recipe authors on NVIDIA's developer forum published a way to run DeepSeek V4.1 Flash on two DGX Sparks instead of four, with a second trick that applies to any headless Spark. I had not run it myself, and the speeds and the one quality check were the author's own.
The benchmarks so far Every result
| Machine | Model | Writing code | Reading (prefill) | Tested |
|---|---|---|---|---|
| Four DGX Sparksgraphics chips capped at 2,200MHz to cut power use | GLM 5.3 FlashNVFP4 at 4 bits, dense layers at 8 | 104.1 tok/s | 3,159 tok/s | 11 Oct 2026 |
| Two DGX Sparksgraphics chips capped at 2,200MHz to cut power use | Qwen 3.8 27BNVFP4 at 4 bits | 44.7 tok/s | 2,034 tok/s | 11 Oct 2026 |
| One DGX Sparkgraphics chips capped at 2,200MHz to cut power use | Qwen 3.8 27BNVFP4 at 4 bits | 26.7 tok/s | 1,188 tok/s | 11 Oct 2026 |
| RTX 4090 desktop | Qwen 3.8 27BQ4_K_M, GGUF | 62.4 tok/s | 1,994 tok/s | 11 Oct 2026 |
| HP ZBook Ultra G1aStrix Halo laptop, Ryzen AI Max+ 395, 64GB | Qwen 3.8 27BQ4_K_M, GGUF | 23.5 tok/s | 194 tok/s | 11 Oct 2026 |
One user, the model's thinking switched off, the same prompts and the same test on each machine. My Sparks would run a little faster than the figures on this page. I cap their graphics chips at 2,200MHz, against about 2,400 uncapped, to cut their power use. When I tested the cap on one box in August, writing speed stayed within 1 per cent, reading was 2 to 4 per cent slower, and the chip's peak power fell from 55.5W to 43.3W. Every figure, the runs with thinking on, the hardware and how I test.
The machines All machines
- NVIDIA DGX Spark A small desktop box with 128GB of memory shared between the processor and the graphics chip, built to run large AI models at home. I run four of them joined together as one.
- RTX Spark laptops and desktops The chip from NVIDIA's DGX Spark in Windows laptops and small desktop boxes. Microsoft opened orders for the first of them on 7 October 2026.
- Apple Mac Studio M5 Ultra Apple's Mac Studio with the M5 Ultra chip. The figures here are Apple's, reviewers' and owners', and each one says whose it is.
- Strix Halo (Ryzen AI Max+ 395) AMD's Ryzen AI Max+ 395, known as Strix Halo. Mine is in an HP ZBook Ultra G1a laptop with 64GB of memory.